
DumboDB is a NoSQL database which aims to be a drop-in replacement for MongoDB Community Edition, with the addition of version control features you expect from Git. This means you can branch and merge for isolated agent workflows, see the history of any document, and push and pull your data to other servers.
Being a drop-in replacement for another product covers several dimensions, the first of which is API functional behaviors, but performance is a critical one as well. At DoltHub, we take performance of all of our products very seriously. You can tell by how much we blog about it!
DumboDB follows in this pursuit, which is signalled by the fact that we started measuring performance at the time of our 0.1.0 release. It was the first blog topic the next week.
Many things have changed in DumboDB since the initial release, and it’s about time to check in on how it compares in performance to our initial release. Spoiler Alert: Dumbo is much faster now!
Version 0.1 Performance Review#
The performance numbers we shared at our initial release were shared mainly as a way to demonstrate that Dumbo wasn’t orders of magnitude worse than MongoDB. There was one access pattern which was 17x worse than Mongo, but most were in the 2x-5x worse range.
The suite had 61 benchmarks, and the post published 30 of them across four categories. None were faster than MongoDB, 11 were green (under 2x), 14 were yellow (2x to 5x), and 5 were red (over 5x).
| Category | Multiplier Range | Green | Yellow | Red |
|---|---|---|---|---|
| Single document reads | 1.43 - 2.12 | 7 | 1 | 0 |
| Single document inserts | 2.62 - 4.53 | 0 | 5 | 0 |
| Single document updates | 3.80 - 17.43 | 0 | 3 | 2 |
| Filters (unindexed) | 2.28 - 7.18 | 0 | 4 | 2 |
| Filters (indexed) | 1.21 - 5.23 | 4 | 1 | 1 |
Reads were the bright spot at about 1.5x. Writes were 2.6x to 4.5x, and updates got worse as documents grew, up to 17.4x for a 1MB document. Indexed equality filters fell behind as collections grew, reaching 5.2x at 50K documents.
This was our baseline to improve upon.
Big Rocks#
While there were several dozen specific changes to make performance better, there were two significant findings which provided the most boost in write performance.
Durable Writes#
The first major thing to call out that is different is that the test harness of the original performance run gave Mongo a significant advantage. By default, a single-node MongoDB instance does not materialize writes to disk.
MongoDB has been called the Snapchat of Databases for this reason. It can’t be trusted in its default configuration because writes are not durable.
I foolishly assumed a database with the success of Mongo would be durable by default, and DumboDB’s writes are durable. Period. There is future work we may consider to allow non-durable writes to DumboDB, but until a user asks for it or an application demands it, we’ll do the safe, correct, and sane thing - which is durable writes.
Once the benchmark system was updated to ensure that Mongo performed durable writes, MongoDB and DumboDB were closer together. It slowed Mongo down by about 30%.
Finally, in full confession, the first set of performance tests were run on a MacBook, and I’ve learned since then that MacBook filesystems aren’t durable at all, so now we run our tests on a Linux host. This is all to say, the 0.1.0 performance results were kinda dodgy.
fdatasync#
The second large change which helped on the write side of the equation
was moving Dolt’s write ahead log to using fdatasync instead of
fsync. For those of you unaware of low-level system calls to write
to disk, you can be forgiven for scratching your head at this.
fsync is a system call which ensures that your data is written fully
to disk before proceeding. It is the critical piece which ensures that
your data is durable (see above). fsync will also update the
metadata about the file, such as the time of the update and the size
of the file. On many file systems, the metadata is stored in a different
block of the disk than the data. This means that fsync at a minimum
needs to write to two places.
fdatasync gives all the guarantees of fsync, but skips metadata that
isn’t needed to read the data back, like timestamps. It still has to
record the file size when the file grows, so Dolt now extends its write
ahead log with zeros ahead of time. This means that for a lot of small
writes, which is what DumboDB does, you can reduce the locations being
touched on disk from two, to one.
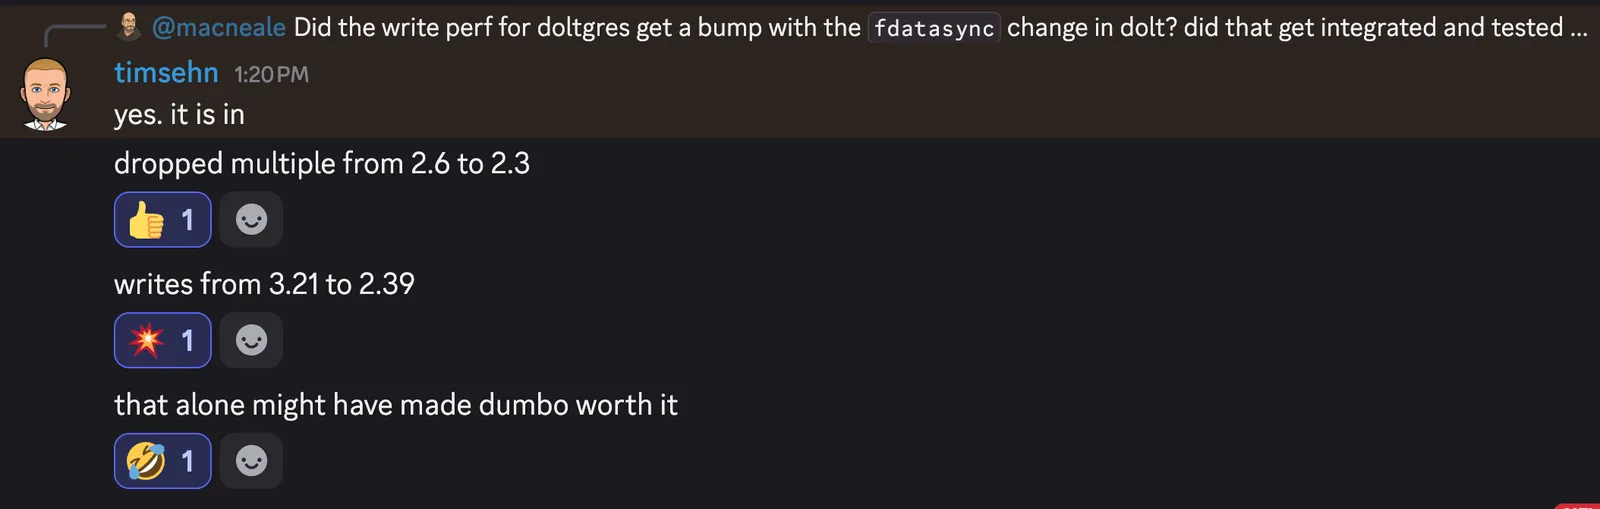
Moving DumboDB to fdatasync cut every write operation nearly in half. Like
magic; 50% improvement.
And it gets better. Since Dumbo depends on Dolt’s storage system for its write ahead log, Dolt’s write latency dropped by 35% in our sysbench write tests, and by 10% to 21% in the mixed workloads. Doltgres also depends on the same code, and it reduced write latency by 25% there.
Of course, my boss was pleased about this. He was so excited, he made Aaron write a blog about it.
Small Rocks#
The two previous improvements are what accounted for most of the write improvements listed below. On the read side of the equation, there was no silver bullet. A major overhaul to indexes which made them more correct, and query planning to take account of those indexes when they exist, were two broad areas that accounted for many of the improvements.
Then there were many one-offs, such as unnecessary memory allocations, trimming out unnecessary round trips for building data structures, and so forth.
All of these changes in concert allow us to show you the improvements below.
Results#
By virtually every measure, DumboDB is closer to parity with MongoDB today. Writes are faster. Reads are faster. By a lot! There is always the question of if we are benchmarking the right behaviors, and we’ll continue to expand the benchmark suite with time.
Summary#
The v0.1 column counts the 30 results published in the May post (the suite had 61 benchmarks then). The v0.8 column is the full run of all 119 benchmarks.
| v0.1 (May) | v0.8 (October) | |
|---|---|---|
| Benchmarks | 61 | 119 |
| Bright green (faster than MongoDB) | 0 of 30 | 49 |
| Muted green (1x to 2x) | 11 of 30 | 66 |
| Yellow (2x to 5x) | 14 of 30 | 4 |
| Red (over 5x) | 5 of 30 | 0 |
| Slowest multiplier | 17.43 | 3.91 |
- No benchmark is over 5x (red) anymore, and only four benchmarks are 2x-5x (yellow).
- DumboDB is faster than MongoDB on 49 of 119 benchmarks. For a small set of operations DumboDB is an order of magnitude faster.
- The primary access patterns of single document read/insert/update show DumboDB is typically 10%-30% slower than MongoDB.
Single Document Reads#
Single document reads are probably the most important access pattern when it comes to what applications do against a database. MongoDB knows this too, which is why it’s hard to beat them on this metric. For smallish documents DumboDB is under a 1.2x multiplier. Larger documents have a lot more variance, but you can expect a 1.5x multiplier or more.
This read path was moderately optimized in the first release, and you can see that improvement happened across the board here, and there may not be a lot of juice left to squeeze.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.1) | Multiplier (v0.8) |
|---|---|---|---|---|
| Find One (int _id) | 311 | 268 | 1.43 | 1.16 |
| Find One (Document _id) | 323 | 275 | 1.47 | 1.17 |
| Find One (ObjectId _id) | 313 | 269 | 1.44 | 1.17 |
| Find One (String _id) | 317 | 273 | 1.47 | 1.16 |
| Find One (1KB result) | 314 | 272 | 1.46 | 1.15 |
| Find One (10KB result) | 351 | 285 | 1.71 | 1.23 |
| Find One (100KB result) | 755 | 426 | 2.12 | 1.77 |
| Find One (1MB result) | 3,633 | 2,341 | 1.96 | 1.55 |
Single Document Inserts#
It’s debatable if inserts or updates are the second most important access pattern.
Regardless, improvements in these operations are much more significant since
our initial release. What’s interesting about these results is that the size of
the document doesn’t have a significant impact on performance. I believe the
10KB insert is directly impacted by the 4MB buffer used by the fdatasync
change. All that said, the worst outlier is the smallest document writes, which
probably points to the overhead of Prolly tree re-writes. 1.28x multiplier
is far better than the 4.3x multiplier.
Dumbo improved, but still has a little to shave here perhaps.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.1) | Multiplier (v0.8) |
|---|---|---|---|---|
| Insert One | 1,817 | 1,424 | 4.28 | 1.28 |
| Insert One (1KB doc) | 2,018 | 1,828 | 3.91 | 1.10 |
| Insert One (10KB doc) | 2,390 | 3,688 | 3.56 | 0.65 |
| Insert One (100KB doc) | 6,454 | 7,041 | 2.62 | 0.92 |
| Insert One (1MB doc) | 40,817 | 37,680 | 4.53 | 1.08 |
Single Document Updates#
Document updates are virtually identical to inserts in the latest version. It turns out it’s pretty hard to be faster than inserts with Prolly trees. You can see for the largest documents, it is faster than an insert because most of the document’s chunks are reused.
Again, massive improvement for Dumbo from our initial release. This was the worst category in v0.1, with the 1MB update at 17.4x. Every size is now between 0.77x and 1.33x, and the 1MB update is 1.18x.
More to shave here? Maybe. We’ll keep at it.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.1) | Multiplier (v0.8) |
|---|---|---|---|---|
| Update One | 1,881 | 1,419 | 3.86 | 1.33 |
| Update One (1KB doc) | 2,082 | 1,742 | 3.80 | 1.20 |
| Update One (10KB doc) | 2,024 | 2,617 | 3.92 | 0.77 |
| Update One (100KB doc) | 2,344 | 1,833 | 6.50 | 1.28 |
| Update One (1MB doc) | 3,534 | 2,992 | 17.43 | 1.18 |
Filtering Queries#
The filtering queries we had in the original plan were mainly to demonstrate that indexes had some impact on performance. Funny story about that. Indexes when we first released were a complete lie.
So while we have some “data” about their performance, we need to remember that in-memory indexes are an entirely different thing than a real Prolly tree index. You can see that Dumbo is staying much more consistent with a secondary index filter always being between a 1.3x and 1.8x multiplier on top of MongoDB performance. In the initial version we were all over the place!
Probably most interesting is how much better Dumbo is without an index. The queries are going slower than indexed queries, don’t be fooled. But why is Dumbo 0.52x of Mongo on larger collections? Query for another day, I suppose.
| Benchmark | Multiplier (v0.1) | Multiplier (v0.8) | Multiplier (indexed, v0.1) | Multiplier (indexed, v0.8) |
|---|---|---|---|---|
| Filter Eq (1K docs) | 2.66 | 1.06 | 1.21 | 1.33 |
| Filter Eq (10K docs) | 5.65 | 1.06 | 4.79 | 1.59 |
| Filter Eq (50K docs) | 7.18 | 1.08 | 5.23 | 1.55 |
| Filter Range (1K docs) | 2.28 | 1.00 | 1.28 | 1.36 |
| Filter Range (10K docs) | 3.20 | 0.53 | 1.68 | 1.47 |
| Filter Range (50K docs) | 4.31 | 0.52 | 1.69 | 1.71 |
New Since 0.1.0#
$lookup#
In MongoDB terms, a $lookup is a SQL JOIN. It’s a way of including data
from another collection in the query results of the collection you are
querying. $lookup benchmarks didn’t exist in v0.1, mainly because
$lookup wasn’t implemented. We’ve implemented them now, so we can
measure how we are doing.
Every metric in this set shows that DumboDB is faster than MongoDB. It’s not immediately clear why this is, but we’ll take it.
We also see an odd performance difference where DumboDB runs laps around Mongo
if you are using $lookup queries which can’t leverage an index. Nested operations
compound this benefit of DumboDB. We obviously want you to use indexes when
possible, but DumboDB will get you a little more mileage if you neglect to.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.8) | DumboDB (indexed) µs/op | MongoDB (indexed) µs/op | Multiplier (indexed, v0.8) |
|---|---|---|---|---|---|---|
| $lookup equality (1K docs) | 3,654 | 4,319 | 0.85 | 2,898 | 3,151 | 0.92 |
| $lookup equality (10K docs) | 16,986 | 25,953 | 0.65 | 3,102 | 3,239 | 0.96 |
| $lookup equality (50K docs) | 76,495 | 2,322,589 | 0.03 | 3,259 | 3,347 | 0.97 |
| $lookup pipeline (10K docs) | 523,333 | 902,473 | 0.58 | 6,961 | 17,391 | 0.40 |
| Nested $lookup (10K docs) | 18,447 | 1,277,129 | 0.01 | 8,781 | 28,208 | 0.31 |
| $graphLookup (10K docs) | 52,223 | 633,166 | 0.08 | 9,996 | 15,800 | 0.63 |
Updates Inside Documents#
After some feedback from a user, we decided to add a set of benchmarks which dealt with nested documents, and updating them. This includes having a sub-document with an array that you continually append to and adding and removing fields continually to a document. These are patterns which show up repeatedly.
What’s most interesting to me is the wide variance here. The size of the document, the depth of the sub-document, and the number of documents all seem to leave us anywhere from 0.5x-2.7x - some of our worst performers are here.
Getting this more consistent across the board is probably an area for improvement. Only a representative sample of results is listed here.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.8) |
|---|---|---|---|
| Array extend (10KB doc, depth 1) | 2,050 | 4,692 | 0.44 |
| Array extend (100KB doc, depth 3) | 3,819 | 4,405 | 0.87 |
| Array extend (1MB doc, depth 1) | 4,229 | 8,052 | 0.53 |
| Array extend (1MB doc, depth 3) | 14,500 | 8,005 | 1.81 |
| Array shorten (10KB doc, depth 1) | 1,882 | 3,708 | 0.51 |
| Array shorten (100KB doc, depth 3) | 499 | 400 | 1.25 |
| Array shorten (1MB doc, depth 5) | 1,337 | 500 | 2.67 |
| Field insert (10KB doc, depth 1) | 2,143 | 3,432 | 0.62 |
| Field insert (100KB doc, depth 3) | 3,693 | 4,818 | 0.77 |
| Field insert (1MB doc, depth 1) | 14,407 | 7,994 | 1.80 |
| Field remove (100KB doc, depth 1) | 1,928 | 4,370 | 0.44 |
| Field remove (1MB doc, depth 5) | 7,928 | 7,850 | 1.01 |
What Is Still Slow#
These are the eight worst results in the standard suite. Bulk inserts stand out the most: inserting 100 documents in one call is 2.43x, and 1,000 documents is 3.91x. Outside the standard suite, shortening an array inside a 1MB document (2.7x, above) is the other result well outside 2x.
| Benchmark | DumboDB µs/op | MongoDB µs/op | Multiplier (v0.8) |
|---|---|---|---|
| Insert Many (1,000 docs) | 56,287 | 14,411 | 3.91 |
| Insert Many (100 docs) | 10,784 | 4,430 | 2.43 |
| $match + $group (indexed) | 2,424 | 1,180 | 2.06 |
| Delete Many (50K docs, indexed) | 159,000 | 78,327 | 2.03 |
| Delete Many (10K docs, indexed) | 34,974 | 17,977 | 1.95 |
| $match + $group | 2,381 | 1,237 | 1.92 |
| Find One (100KB result) | 755 | 426 | 1.77 |
| Filter Range (50K docs, indexed) | 7,736 | 4,535 | 1.71 |
Conclusion#
Hopefully it’s clear that we are working hard to make DumboDB competitive in performance with MongoDB. When you add on the ability for DumboDB to branch and merge like Git, why not give it a whirl?
If you find something slow, we’d love an issue!
Come chat with all of DoltHub’s dev team on our Discord, and tell us what you’re building!